Documents answer "what are the hours". They cannot answer "who has waited the longest right now", because the answer changes every minute and lives in the queue table, not in a markdown file. This part gives the staff assistant one function it may call, wires the call through the same abstraction the rest of the season uses, and then builds the guard that decides, in code, when the function is even on the table. Along the way the local model answered in Thai, which turned out to be the most useful thing it did.
One function, described for a model
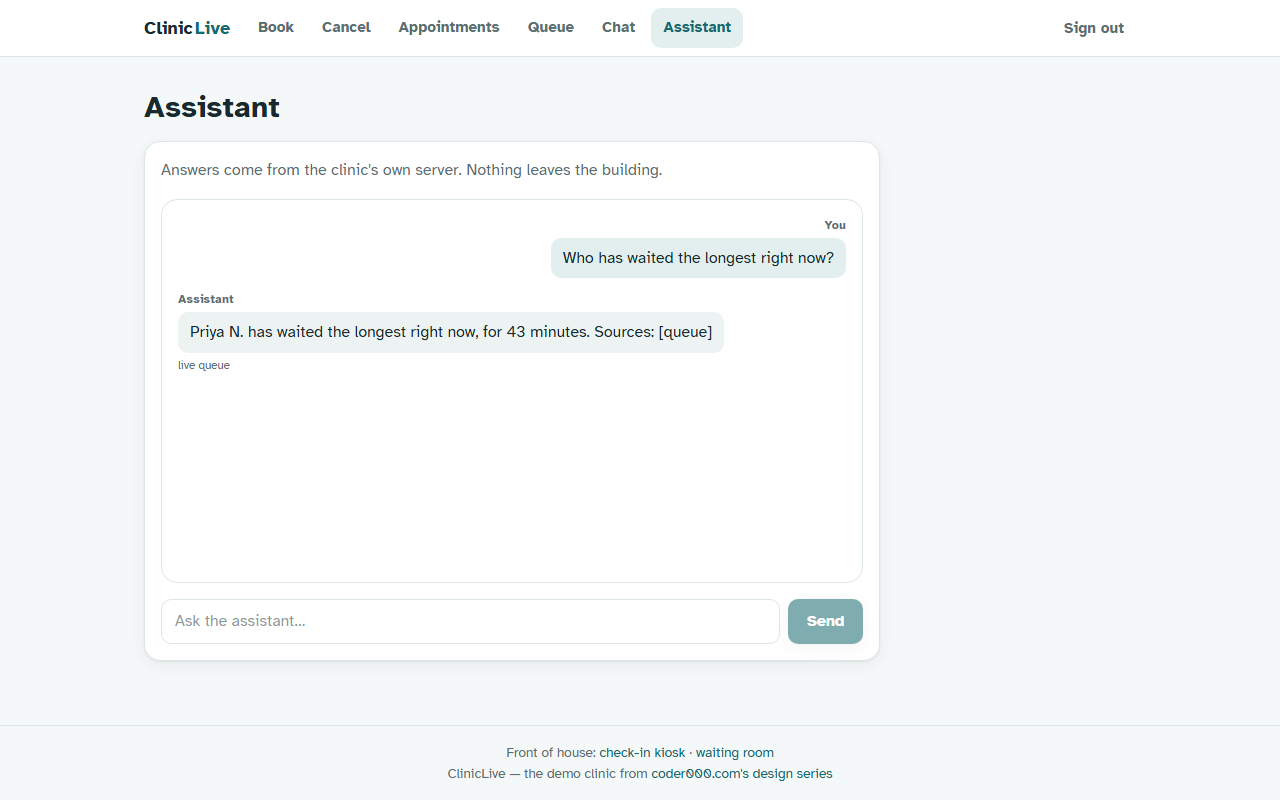
Microsoft.Extensions.AI lets an ordinary method become a tool: AIFunctionFactory wraps it, its parameters become the schema, and its description tells the model what it is for. The clinic's one function is get_queue(status), over the QueueService from season one. It returns a compact list, first name and initial, confirmation code, minutes waited and status, longest first, and nothing else: no surnames, no phone numbers. The masking happens in the service, before the data reaches the prompt, because anything in the prompt can end up in an answer. The description says, in plain words, that the function is only for questions about the current queue or waiting times.
builder.Services.AddSingleton<IChatClient>(sp =>
    new ChatClientBuilder(new OllamaApiClient(new Uri(ai.Endpoint), ai.ChatModel))
        .UseFunctionInvocation()
        .Build(sp));
The function-invocation wrapper runs the loop: the model asks for the tool, the wrapper executes it and feeds the result back, the model writes the answer. Streaming survives the loop. The answer ends with "Sources: [queue]" so the citation guard from Part 7 is satisfied, and the page renders it as "live queue".
The guard: a tool is offered, not available
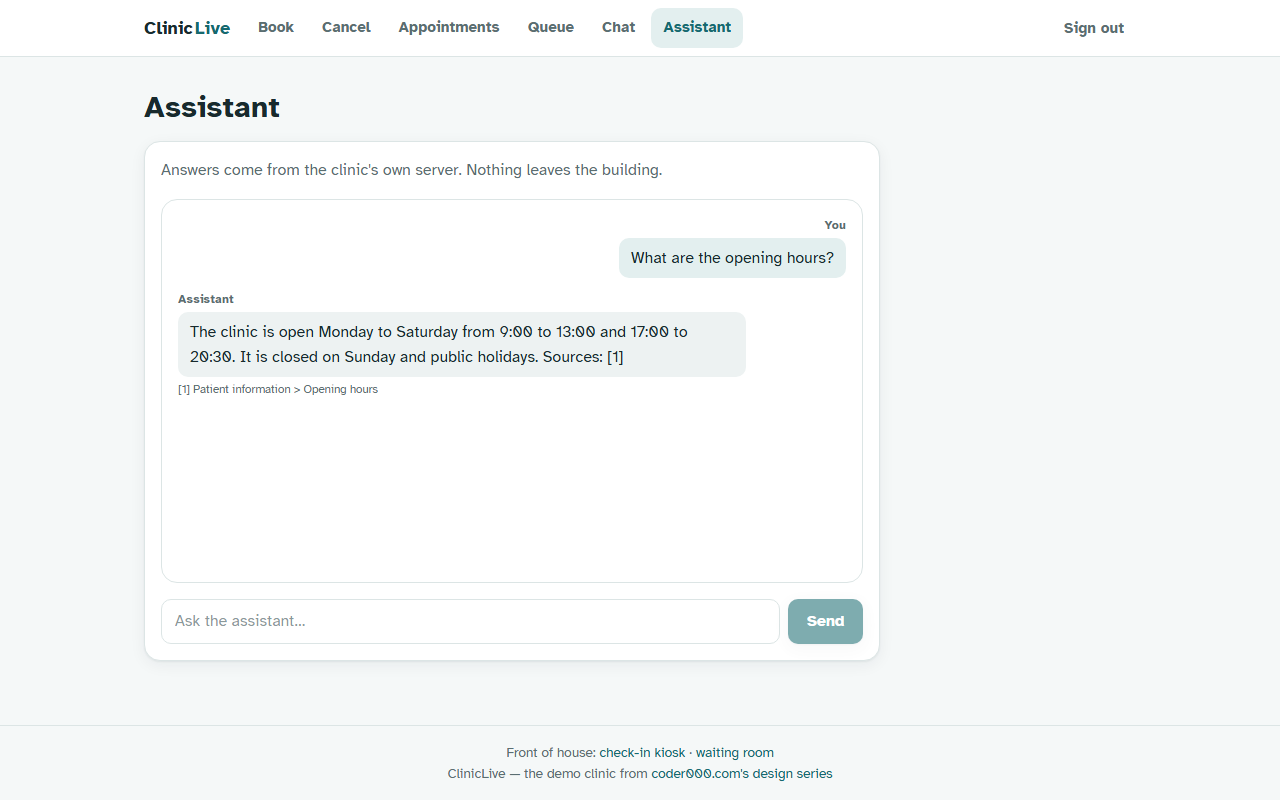
Part 2's exam found the problem this section solves: offered a queue function and asked about opening hours, Llama called the function anyway. A model that reaches for a tool whenever one is present makes every answer slower and some answers stranger, and the cure is not a sterner prompt. The service classifies each question with a deterministic check for queue words, and only then adds the tool to the request; every other question is sent with no tools at all, and the log says which path was taken. The patient assistant in Part 9 never receives a tool under any classification, and the code says so in a comment where the next developer will read it.
Four things that went wrong
An extension method that would not resolve. Writing the builder's type name in full does not import the namespace its extension methods live in; the file needed a using directive. Two minutes, and a reminder that fully-qualified names are not a substitute for imports.
Part 7 had locked the door. Retrieval's rule, "nothing near enough, refuse without calling the model", is right for documents and wrong for the queue: no document is near "who has waited longest", so every queue question was refused before the tool could be offered. The tools path now skips that shortcut. Each part's sensible rule can be the next part's bug.
A test that booked someone else's slot. The new integration test seeded an appointment at a time an older test already used, and the two collided. Each test now books its own hour. Test data is shared state whether you meant it to be or not.
The Thai preamble. On one run the model, before calling the tool, wrote a sentence of narration in Thai. The page painted it as it streamed, the tool ran, the answer followed, and the guard saw a bubble that started with uncited text and replaced the whole thing with the refusal. Adding "Always answer in English" to the prompt did not stop it. The fix is in code: when the stream reports a function call or a function result, the page retracts whatever was painted before it. Models do odd things around tool calls; the application decides what the user sees.
Do it yourself
One tool, the loop that runs it, and the gate in front of it. Tag private-08.
- Write the function the model may call. The description is what the model reads; the masking happens before the data reaches it:
public const string GetQueueName = "get_queue"; public const string GetQueueDescription = "Returns the patients in the clinic queue right now with how long each has waited, " + "longest first. Only for questions about the current queue or waiting times."; public AIFunction GetQueueFunction() => AIFunctionFactory.Create(GetQueueAsync, GetQueueName, GetQueueDescription); public async Task<IReadOnlyList<QueuePatient>> GetQueueAsync( [Description("Which part of the queue to report: \"waiting\", \"called\" or \"done\".")] string status = "waiting", CancellationToken ct = default) { var lines = await queue.GetLinesAsync(status, ct); // first name + initial, code, minutes, status ... } - Wrap the chat client so a tool call is executed and fed back automatically, and import the namespace the extension method lives in; a fully qualified type name does not do that for you:
using Microsoft.Extensions.AI; builder.Services.AddSingleton<IChatClient>(sp => new ChatClientBuilder(new OllamaSharp.OllamaApiClient(new Uri(ai.Endpoint), ai.ChatModel)) .UseFunctionInvocation() .Build(sp)); builder.Services.AddScoped<AssistantTools>(); - Decide in code when the tool is even offered. A regex, not a prompt:
private static readonly Regex QueueQuestion = new( @"\b(queue|waiting|waited|wait|called|next|longest)\b|how many patients", RegexOptions.IgnoreCase | RegexOptions.CultureInvariant); var withTools = audience == KnowledgeAudience.Staff && IsQueueQuestion(question); var options = withTools ? new ChatOptions { Tools = [tools.GetQueueFunction()] } : null; - Let the tools path bypass the "nothing near enough" refusal from Part 7, because no document is ever near "who has waited longest"; the condition
usable.Count == 0 && !withToolsin Part 7's section is that bypass. - Tell the model, on the tools path only, to cite
Sources: [queue], accept that in the guard, and render it as "live queue". - On the page, clear the bubble when the stream reports a function call or result, so anything the model said on the way to the tool disappears (the
ResetMarkerbranch in Part 5's loop). Adding "always answer in English" to the prompt did not stop the Thai; this did. - Test with a fake chat client that returns a tool call then an answer, and assert the patient audience is never offered tools; then check two patients in at the kiosk and ask the staff page who has waited longest.
What you should see: a name and a wait in minutes, cited as "live queue", and in the console one line saying "tools offered" for that question and "no tools" for an opening-hours question.
The brief that built it, trimmed to the lines that decided the result. Season one put every prompt in a commit message; this season's briefs were written to a coding assistant before each part, and this is what they said.
Services/Ai/AssistantTools.cs: get_queue(status) via AIFunctionFactory over QueueService, returning first
name and initial, code, minutes waited, status, longest first; never full names or phones. Wrap the OllamaSharp
client with ChatClientBuilder(...).UseFunctionInvocation(). Offer the tool only for staff, and only when a
deterministic classifier sees queue words; log which path. Tool answers cite "[queue]"; the guard accepts it;
the page shows "live queue". Tests: classifier (five and five), a fake client returning a tool call executed
against two seeded patients, patient audience never gets tools. Smoke test with two real check-ins.
Perishable facts, as of September 2026: Qwen 2.5 14B through Ollama's native tools API; Gemma 3 is refused tools by Ollama, and Llama 3.1 over-calls them, both per Part 2. Microsoft.Extensions.AI 10.10 and OllamaSharp 5.4; the function-invocation wrapper's name and namespace are the current ones.
Model pick: the guard-in-code decision came from the brief; the build ran on the cheaper model and was the season's longest, at twenty-five minutes and over a hundred tool uses, most of them spent on the Thai preamble.
What the AI got wrong: the local model narrated in a language nobody asked for; the coding assistant missed a using, tripped over its own earlier rule, and collided with an older test. All four are recorded above because all four will happen to you.
The meter: a tool-backed answer costs two model turns instead of one, roughly four seconds on the GPU, still well inside a receptionist's patience. The build meter for this part is the largest of the season; the retro has the number.
Checkpoint: tag private-08 in
the repo. Check two
patients in at the kiosk, then ask the staff assistant who has waited longest; then
ask it the opening hours and confirm the console log shows no tools were offered.
Next: the patient's side.