Part 6 put the clinic's knowledge in the database. This part makes the assistant use it: find the passages nearest to the question, hand them to the model with the question, insist on a citation, and refuse in one fixed sentence when the documents do not answer. The first-time-patient question from Part 5 gets asked again, and this time the answer is the clinic's. Along the way the guard that enforces citations threw away a perfectly good answer, which is the mistake this part is really about.
Retrieval: one query, and the audience lives in the WHERE clause
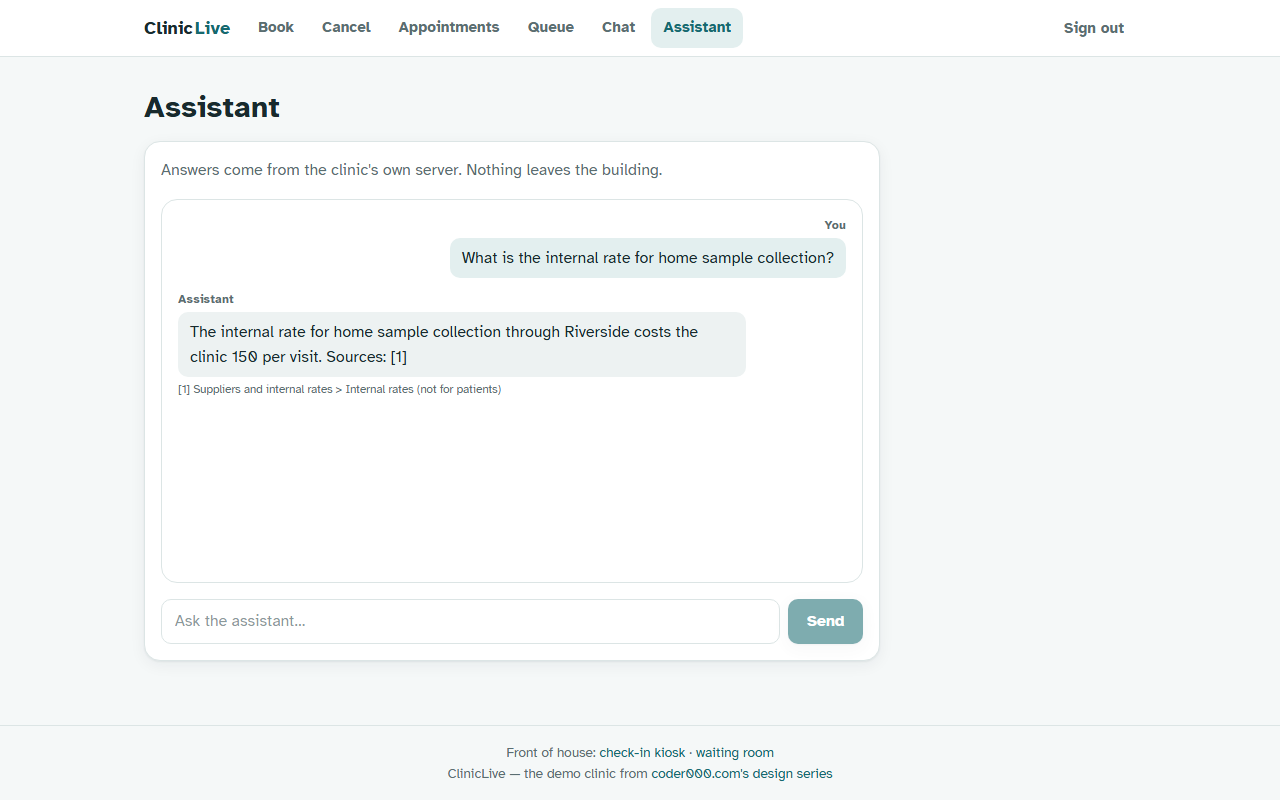
The retriever embeds the question with the same model that embedded the chunks, then asks PostgreSQL for the nearest chunks by cosine distance, joined to their documents. Two rules are enforced in that query rather than anywhere else. First, the audience: a public question may only see public documents; a staff question sees both. It is a WHERE clause on the document row, and an unknown audience fails closed to public. There is no code path where a chunk is fetched and then filtered in memory, because that is the path a future refactor forgets. Second, a distance cut-off: chunks further than 0.55 are dropped before the model sees anything, and if nothing survives, the model is not called at all; the refusal is returned directly and the log says why. Six chunks at most go into the prompt.
The prompt the model actually sees
The system prompt from Part 5 gains three sentences: answer only from the documents; end the answer with a line "Sources:" naming the numbers used; if the documents do not answer, reply with exactly "I don't know that; please ask reception." and nothing else. The user message becomes an instruction block, then "CLINIC DOCUMENTS:" with each chunk numbered and headed by its document title and heading, then "QUESTION:" and the question. The headings are the ones the chunker preserved in Part 6; without them the model would be reading "600" with no idea what it is the price of.
The guard, and the answer it threw away
The spec's rule is strict: every answer shown to a user carries a citation or the fixed refusal, never neither. The model is asked to follow it, but a model is asked, not made. So a guard in the service checks the finished text: no "Sources:" and not the refusal sentence means the shown answer becomes the refusal, and the original goes to the log with the question, where a human can decide whether the documents need a new section. Because the answer streams, the guard cannot rewrite what the user has already watched appear, so it sends one final marker delta and the page replaces the bubble's text.
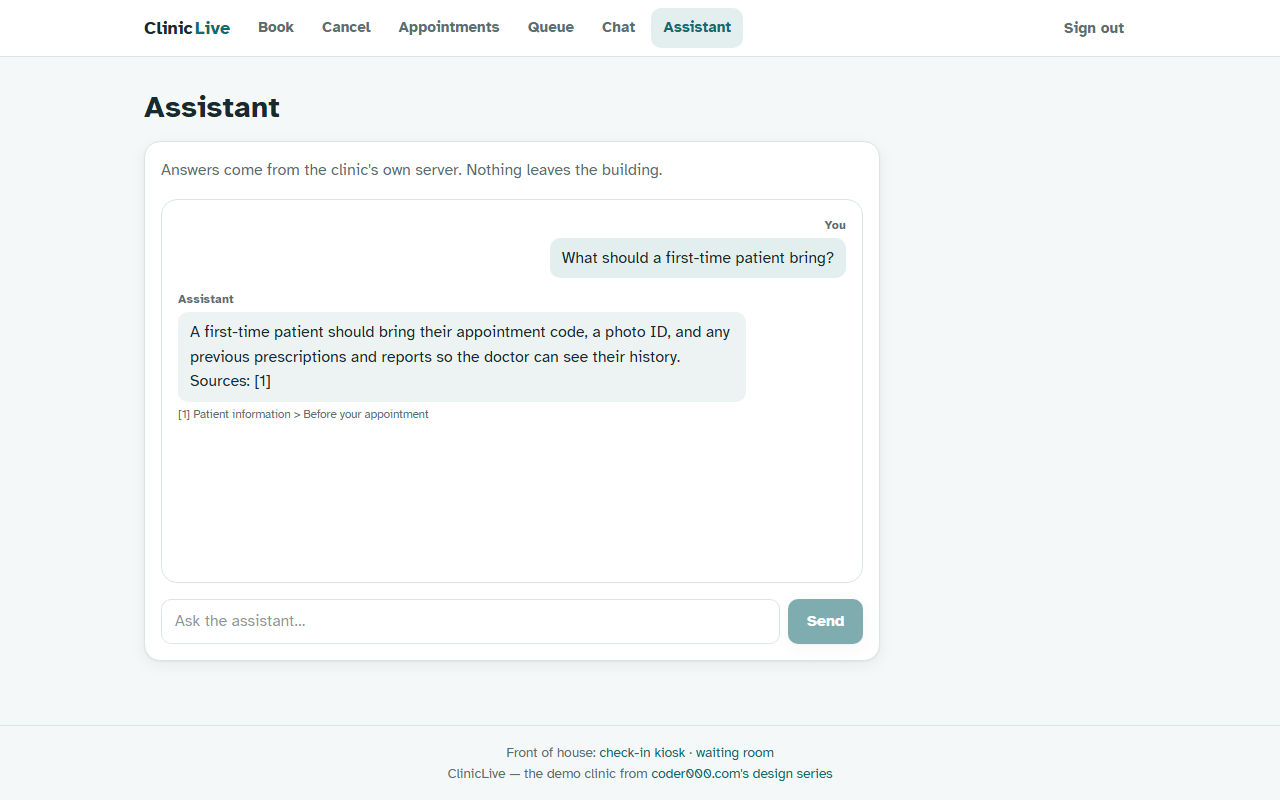
The first version of the guard looked for a line starting with "Sources:". Qwen writes it inline, at the end of the last sentence: "…so the doctor can see their history. Sources: [1]". So the very first live answer, the correct one in the screenshot above, was judged uncited and shown as the refusal. Reading the log made it obvious; the fix looks for the last "Sources:" marker anywhere and reads to the end of the line, and a regression test now feeds an inline citation through the guard. This is the season's most instructive mistake so far: a rule enforced in code is only as good as the code's idea of what compliance looks like, and the model's idea was reasonable.
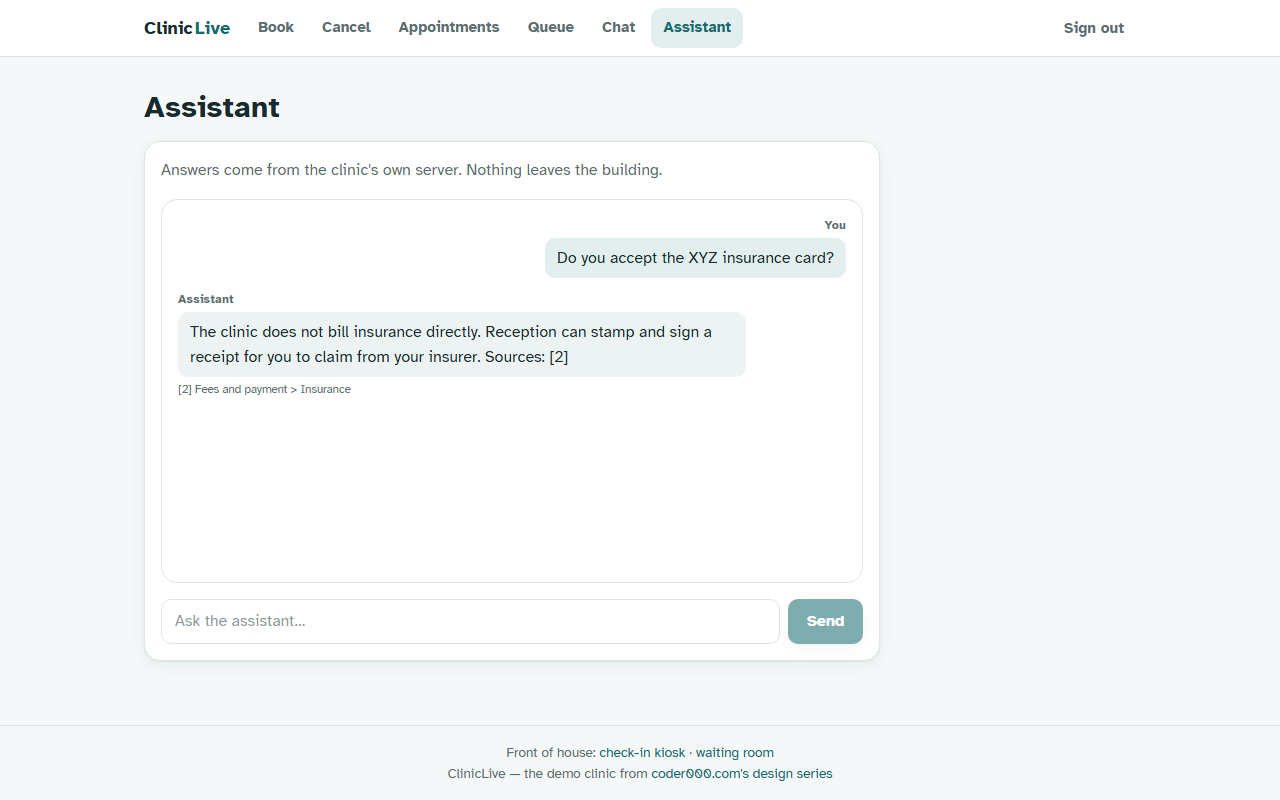
Three questions, three behaviours
What the tests pin down
Three integration tests use the fake embedding generator from Part 6, so none of them needs a model. A staff chunk is returned for a staff question and not for a public one, using the chunk's own text as the question so the distance is exactly zero. An uncited answer from a fake chat client becomes the refusal. And a question whose nearest chunk is beyond the cut-off yields the refusal without the chat client being called at all, checked with a fake that throws if it is. Forty-five tests, all green.
Do it yourself
Retrieval, the prompt, and the guard, in the order you would write them. Tag private-07.
- Write the retriever. One query does the audience filter and the ranking; nothing is filtered in memory afterwards:
var visible = audience == KnowledgeAudience.Staff ? db.KnowledgeChunks.Where(c => c.Document.Audience == KnowledgeAudience.Staff || c.Document.Audience == KnowledgeAudience.Public) : db.KnowledgeChunks.Where(c => c.Document.Audience == KnowledgeAudience.Public); var found = await visible .AsNoTracking() .OrderBy(c => c.Embedding.CosineDistance(vector)) .Take(take) .Select(c => new RetrievedChunk( c.Id, c.Document.Title, c.Document.Slug, c.Heading, c.Text, c.Embedding.CosineDistance(vector))) .ToListAsync(ct); - Drop what is too far away, and skip the model entirely when nothing is left:
var usable = found.Where(c => c.Distance <= options.MaxDistance).ToList(); if (usable.Count == 0 && !withTools) { return new AssistantReply(Only(RefusalText), []); } - Extend the system prompt with the grounding contract. These are the lines the model actually obeys:
Every question arrives with numbered CLINIC DOCUMENTS. They are the only knowledge you have; answer from them and from nothing else you may think you know. End every answer with one final line naming the numbers you used, like this: Sources: [1], [3] If the documents do not answer the question, reply with exactly this sentence and nothing else, with no Sources line: I don't know that; please ask reception. - Lay out the user message the same way every time: an instruction block, then
CLINIC DOCUMENTS:with each chunk as[n] Title > Headingand its text, thenQUESTION:. The instruction block repeats the rule next to the documents, which is where a 14B model reads it:Answer the question using only the clinic documents below. Quote no document number you did not use, and invent no detail they do not contain. Finish with a line: Sources: [1], [2] If the documents do not answer the question, reply with exactly: I don't know that; please ask reception. - Write the guard so it finds a citation anywhere, not only on its own line. This is the version after the bug:
private static string? SourcesLine(string answer) { var start = answer.LastIndexOf("Sources:", StringComparison.OrdinalIgnoreCase); if (start < 0) return null; var end = answer.IndexOf('\n', start); return (end < 0 ? answer[start..] : answer[start..end]).Trim(); } // after the stream has finished: if (!HasCitation(text) && !CitesQueue(text) && !IsRefusal(text)) { logger.LogInformation("Uncited answer replaced by the refusal. Question: {Question} Answer: {Answer}", question, text); yield return GuardMarker; // the page swaps the bubble for the refusal } - Handle
GuardMarkerin the page (the loop in Part 5's section) and render the citations under the bubble from the chunks the reply carries. - Write the three tests with the fake embedder from Part 6: a staff chunk returned for staff and not for public; an uncited answer becomes the refusal; a far-away nearest chunk yields the refusal without a model call.
What you should see: the first-time-patient answer now names the appointment code and cites the patient information page; a question outside the documents gets the fixed sentence with no source line. If a correct answer turns into the refusal, read the log line before touching the prompt.
The brief that built it, trimmed to the lines that decided the result. Season one put every prompt in a commit message; this season's briefs were written to a coding assistant before each part, and this is what they said.
KnowledgeRetriever.SearchAsync: embed the question, order by cosine distance, filter audience in a Where on
the document row (public: only public; staff: both), take MaxContextChunks. AssistantService: retrieve, build
the user message as instruction block + "CLINIC DOCUMENTS:" [n] title > heading + text + "QUESTION:", extend
the system prompt to answer only from the documents, end with "Sources: [n]", or reply with exactly the
refusal sentence. Guard after streaming: no Sources line and not the refusal means the shown answer becomes
the refusal and the original is logged. Ai:MaxDistance 0.55; nothing within it means no model call. Tests:
visibility, the guard, the distance cut-off with a fake chat client that throws if called.
Perishable facts, as of September 2026: the 0.55 cosine cut-off was chosen from Part 2's hit-and-miss table for nomic-embed-text and will be wrong for a different embedding model; re-measure it when the model changes. Six chunks fits a 4,096-token context with room for the answer.
Model pick: the retrieval rules, the citation contract and the guard were designed at high effort in the brief; the build ran on the cheaper model, which also found and fixed the inline-citation bug once it read the log.
What the AI got wrong: the guard's definition of a citation. The local model did nothing wrong in this part at all; every answer was grounded and cited. And one human mistake from the documents themselves: writing an Insurance section into the fees page and then expecting an insurance question to be refused.
The meter: a grounded answer costs one embedding call plus one generation with about 600 tokens of context, two seconds on the GPU. The build meter continues to accumulate for the retro; this was the longest build so far.
Checkpoint: tag private-07 in
the repo. Ask the staff
assistant what to bring and compare with the answer you saved in Part 5. Then ask it
something the documents do not cover, such as which doctor is on duty tomorrow, and
you should get the fixed sentence. Next: a live question about the queue.